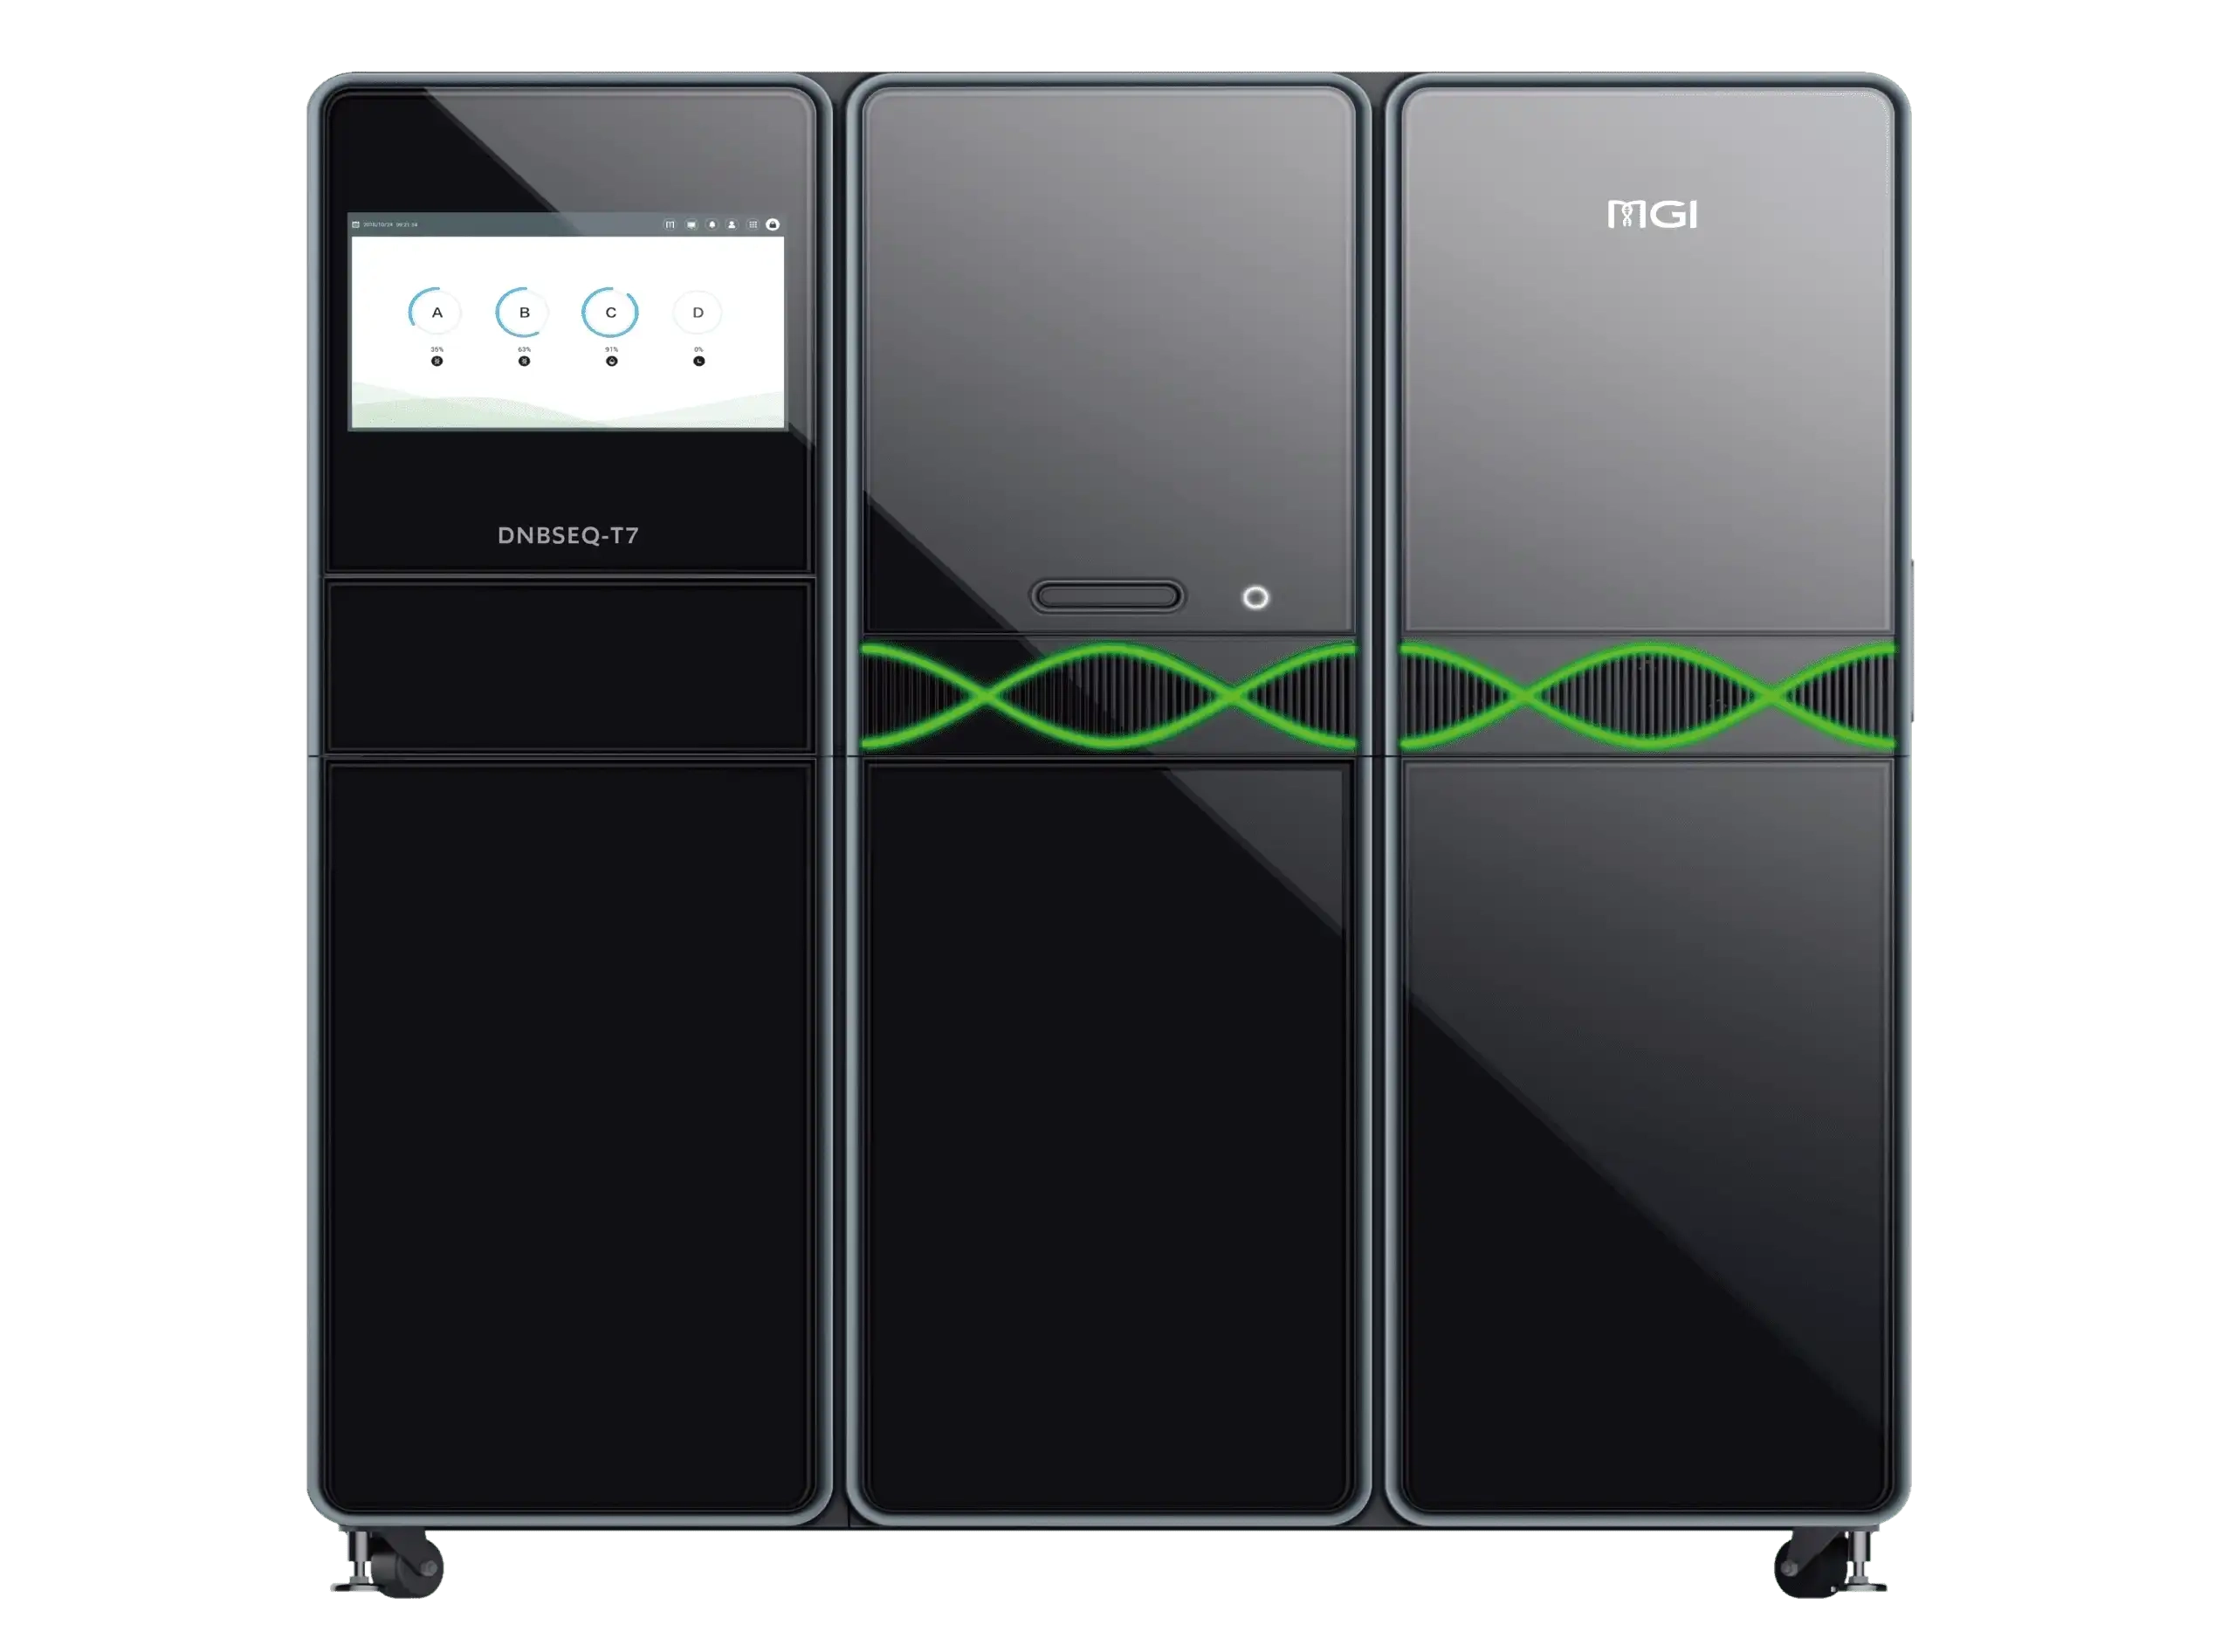
DNBSEQ-T7
The DNBSEQ-T7 is a state-of-the-art ultra-high-throughput sequencer delivering up to 6 TB of high-quality data daily across four independent flow cells. Built on DNBSEQ™ technology, it suits whole-genome, deep exome, transcriptome, and epigenome sequencing at large scale with exceptional speed and flexibility.
Manufacturer: MGI — Latvia
Overview
The DNBSEQ-T7 is a state-of-the-art genomic sequencer designed to meet the demands of data-intensive studies, including whole-genome, deep exome, transcriptome, and epigenome sequencing. Using advanced DNBSEQ™ technology alongside sophisticated biochemical, fluidic, and optical systems, it delivers up to 6 TB of high-quality data daily, offering ultra-high throughput, speed, and flexibility. Ideal for large-scale sequencing projects, the DNBSEQ-T7 efficiently handles multiple tasks in parallel, accelerating research with exceptional data output.
Core DNBSEQ™ Sequencing Technology
DNBSEQ™ Technology combines DNA nanoball (DNB) rolling-circle amplification with patterned array loading and combinatorial probe-anchor synthesis (cPAS). Because each DNB is a clonal copy that does not amplify during sequencing, the chemistry avoids the error accumulation, index hopping, and duplication of bridge-amplification platforms, delivering high accuracy with low duplication rates. All MGI sequencers can run as standalone systems from sample to result without any network connection, keeping data fully secure.
Key Highlights
Up to 6 TB of data daily and up to 24 billion reads per run, processing up to 60 whole human genomes per day.
Four independent flow cells run at any time, each acquiring up to 5,000M reads, with PE100 or PE150 selectable per flow cell.
Precision you can trust: no clonal errors or index hopping, with greater than 99% SNP and indel precision and sensitivity.
PE150 completed in 24 to 30 hours; up to 20,000 genomes at 30× coverage annually.
Flow Cell Mastery
The DNBSEQ-T7 features four independent flow cells that can run at any time, eliminating the need to batch large sample quantities. Handle one to four flow cells concurrently, acquiring up to 5,000M reads per unit, and choose PE150 or PE100 for each flow cell to tailor throughput and read length to each project.
Applications
Whole-genome sequencing, deep exome sequencing, gene expression, transcriptome sequencing, methylation analysis, metagenomics, population studies, and multiomics.
Data Security and Bioinformatics
Every MGI platform can operate as a standalone system from sample to result with no network connection, eliminating the risk of data breaches. On the analysis side, MGI's bioinformatics accelerators speed up secondary analysis: MegaBOLT reduces computational delays by up to 20 times over classical algorithms, and ZBOLT Pro, the ultra-high-performance version, achieves up to a 200 times increase in data analysis speed.
Specifications
| Specification | DNBSEQ-T7 |
|---|---|
| Data Output | 1.16 Tb to 7 Tb per run (up to 6 TB per day) |
| Flow Cells per Run | 1 to 4 (independent) |
| Reads per Flow Cell | 5.8B (up to ~24 billion reads per run) |
| Read Length | PE100, PE150 |
| Run Time | 16 h to 24 h |
| Q30 Quality | ≥85% |
| Throughput | Up to 60 whole human genomes per day; up to 20,000 30× genomes annually |
| Accuracy | No clonal errors or index hopping; >99% SNP/indel precision and sensitivity |
| Sequencing Technology | DNBSEQ™ (DNA nanoball, cPAS) |
| Typical Applications | WGS, deep exome, transcriptome, epigenome, metagenomics, population studies, multiomics |